Reading NetCDF4 Data in Python (codes included)
A temperature field usually needs more than a column of numbers. We also need to know where each value belongs, when it was measured, and whether it is in kelvin or degrees Celsius. NetCDF keeps these arrays and their descriptions together. It is widely used for climate, ocean, and other geoscientific data.
In this tutorial, we will open a small NetCDF file, inspect its structure, read selected values, and make a plot. The file contains synthetic teaching data, not observations or a forecast. You can download it directly or create it using the companion writing NetCDF tutorial.
The Python package is called netCDF4, but it also reads older NetCDF formats. NetCDF-4 files use HDF5 storage; older NetCDF-3 files do not. You can check the format rather than infer it from the .nc extension. See Unidata’s explanation of the formats.
Get the example and install the packages
Download example.nc and the complete reading script into the same working directory. The sample has three time steps, five latitudes, and six longitudes. One value is deliberately missing so we can see how it is handled.
For a new Python environment on macOS or Linux:
python3 -m venv .venv
source .venv/bin/activate
python -m pip install netCDF4 numpy matplotlib
python read_netcdf.py example.nc
On Windows, create the environment with py -m venv .venv, then activate it in PowerShell with .venv\Scripts\Activate.ps1. If you already use conda, conda install -c conda-forge netcdf4 numpy matplotlib is another option. Use one environment consistently for installation and execution.
First inspect the structure
Before reading a large array, find out what its axes represent:
from netCDF4 import Dataset

with Dataset("example.nc", "r") as ds:
    print("Format:", ds.data_model)
    print("Variables:", list(ds.variables))
    for name, dimension in ds.dimensions.items():
        print(name, len(dimension), dimension.isunlimited())

    temperature = ds.variables["temperature"]
    print(temperature.dimensions)
    print(temperature.shape)
    print(temperature.units)
The temperature variable has dimensions ('time', 'lat', 'lon'), shape (3, 5, 6), and units K. These tell us how to interpret its indices. The first index chooses a time; the next two locate a grid point.
A dimension defines an axis and its length. A variable stores values over one or more dimensions. An attribute describes a variable or the whole dataset. In this example, the one-dimensional coordinate variables lat, lon, and time provide the actual coordinate values. A dimension named lat alone would not tell us which latitudes it represents.
The with block closes the file automatically, including when an error occurs inside the block. Read arrays and copy any needed attributes before leaving it. A NetCDF variable is an object attached to an open file; it is not itself an in-memory NumPy array.
Read a slice and keep its coordinates
We rarely need every value in a large model output file just to inspect one map. Here we read the first time step:
from netCDF4 import Dataset

with Dataset("example.nc") as ds:
    temperature = ds.variables["temperature"]
    first_slice = temperature[0, :, :]
    latitudes = ds.variables["lat"][:]
    longitudes = ds.variables["lon"][:]
    units = temperature.units

print(first_slice.shape)  # (5, 6)
The colon means all values along that axis. Thus the selection takes one time and all latitudes and longitudes. first_slice is now an array and remains usable after the file closes. In contrast, attempting another read through temperature outside the block will fail because its file is closed.
Basic slices look like NumPy indexing, but advanced indexing is not identical. In particular, the netCDF4 interface treats index arrays independently along their dimensions. When a selection gets complicated, start with a small slice and check its shape. The netCDF4 indexing documentation gives examples.
Keep missing values out of calculations
The sample uses a fill value of -9999 for its missing cell. With the default netCDF4 settings, reading the variable produces a masked array, so the missing value is excluded from its mean:
import numpy as np

print("Missing cells:", np.ma.getmaskarray(first_slice).sum())
print("Mean temperature (K):", first_slice.mean())
This reports one missing cell. If another library expects ordinary floating-point arrays with NaN for missing data, convert deliberately:
values = np.ma.asarray(first_slice, dtype=float).filled(np.nan)
print(np.nanmean(values))
Do not replace missing temperatures with zero or silently discard the mask. Either operation can change the scientific meaning of a mean, minimum, or map. Inspect the variable’s attributes when a new dataset behaves unexpectedly. Packed variables may also use scale_factor and add_offset, which netCDF4 normally applies automatically when reading.
Decode the time coordinate
The values 0, 6, and 12 in our file are hours since midnight on January 1, 2026. They are not Unix timestamps. Read the reference time and calendar from the file:
from netCDF4 import Dataset, num2date

with Dataset("example.nc") as ds:
    time = ds.variables["time"]
    dates = num2date(
        time[:],
        units=time.units,
        calendar=getattr(time, "calendar", "standard"),
    )

for date in dates:
    print(date.strftime("%Y-%m-%d %H:%M:%S"))
The output is January 1, 2026 at 00:00, 06:00, and 12:00. This sample uses UTC. Climate-model files may instead use calendars such as 360_day or noleap; preserve that calendar rather than forcing every date into Python’s standard calendar. num2date can return calendar-aware cftime objects for this reason. The CF time-coordinate guidance explains the metadata involved.
Select a point on this grid
For our separate one-dimensional latitude and longitude axes, we can choose the nearest coordinate on each axis:
import numpy as np
from netCDF4 import Dataset

with Dataset("example.nc") as ds:
    latitudes = ds.variables["lat"][:]
    longitudes = ds.variables["lon"][:]
    iy = int(np.abs(latitudes - 37.2).argmin())
    ix = int(np.abs(longitudes - (-122.2)).argmin())
    series = ds.variables["temperature"][:, iy, ix]

print(latitudes[iy], longitudes[ix])  # 37.0, -122.0
print(series)                       # approximately 280.6, 281.1, 281.6 K
This selects a grid cell; it does not interpolate to the requested location. It is also not a general geographic nearest-neighbor method. Our small regular grid makes the coordinate selection easy to understand.
Ocean products such as RTOFS may have two-dimensional Latitude(Y, X) and Longitude(Y, X) arrays. Their X and Y axes are grid indices, not geographic coordinates. For those files, inspect the coordinate arrays and use a geographic-distance method appropriate to the grid. Simple squared differences in degrees can give misleading results near the dateline or poles. Check the longitude convention, land mask, and vertical levels too: the first depth index is not automatically the sea surface in every product.
Plot the first time step
Using the first_slice, latitudes, and longitudes loaded above:
import matplotlib.pyplot as plt

fig, ax = plt.subplots(figsize=(6, 4), constrained_layout=True)
cmap = plt.get_cmap("viridis").copy()
cmap.set_bad("0.85")
image = ax.pcolormesh(longitudes, latitudes, first_slice,
                     shading="auto", cmap=cmap)
ax.set_xlabel("Longitude (degrees east)")
ax.set_ylabel("Latitude (degrees north)")
fig.colorbar(image, ax=ax, label="Temperature (K)")
fig.savefig("temperature.png", dpi=200)
plt.show()
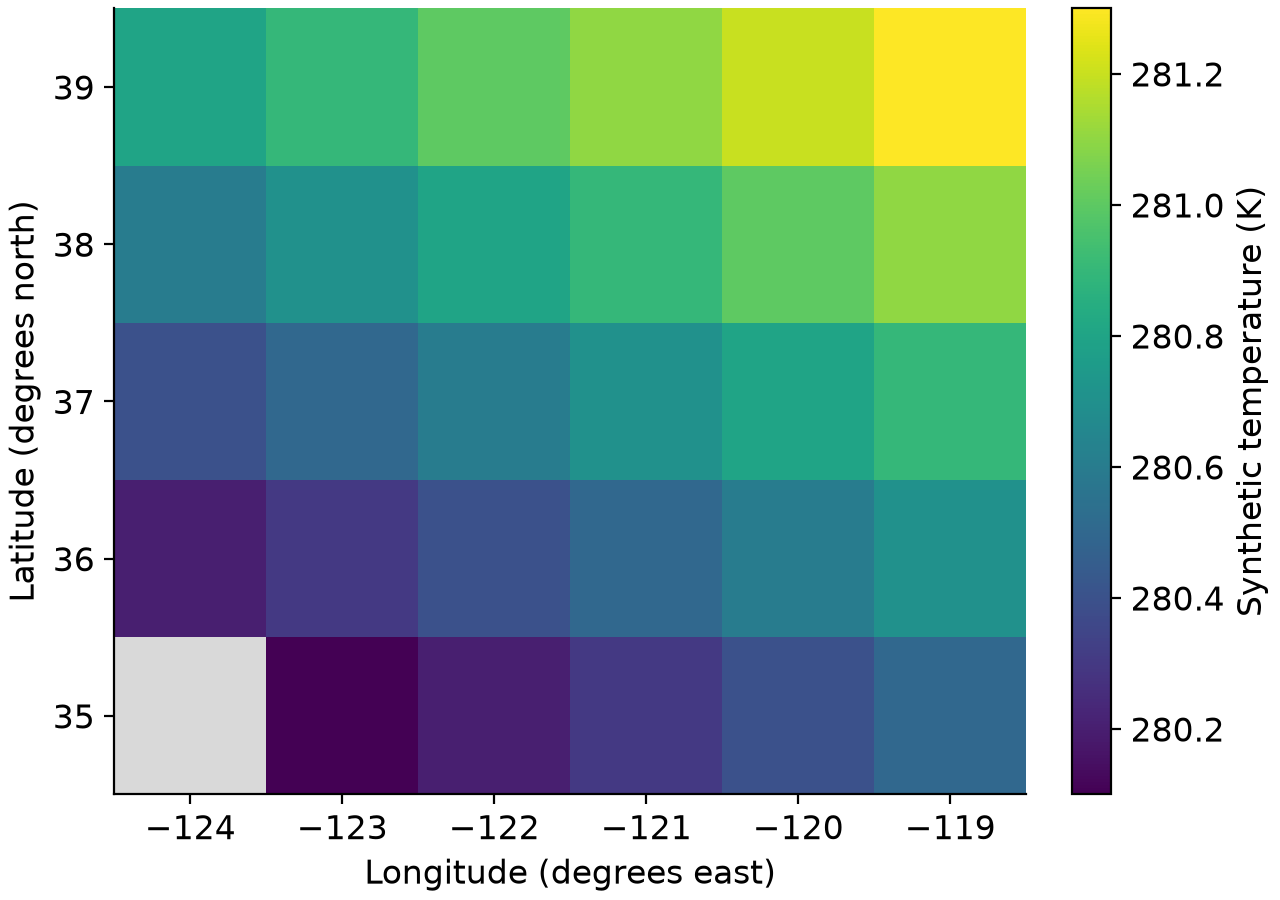
The missing cell is gray. The axes use the coordinates from the file rather than row and column numbers. This is a simple coordinate plot, not a projected map; use a mapping library when projection and geographic context matter. The complete plotting script reads the sample and saves the figure below.
Remote files and xarray
The same inspection habit helps with remote data. A compatible OPeNDAP service can provide slices without downloading the complete dataset, but its service URL differs from an ordinary webpage or file-download link. Availability, authentication, and the netCDF library’s OPeNDAP support also matter. For a reproducible study, record the dataset version and actual time range rather than relying on a changing “latest forecast” endpoint.
For work organized around named dimensions, xarray can make selections more readable. Install it with python -m pip install xarray, then try:
import xarray as xr

with xr.open_dataset("example.nc", engine="netcdf4") as ds:
    point = ds["temperature"].sel(lat=37.2, lon=-122.2,
                                  method="nearest").load()
print(point)
Here, load() brings the selected values into memory before the file closes. Xarray also decodes common time and missing-value metadata. The lower-level netCDF4 workflow remains useful when you need to inspect exactly how a file is structured.
Further reading
- Complete reading script and sample NetCDF file.
- Writing NetCDF4 data using Python, including the script that creates this sample.
- Unidata’s netCDF4-Python tutorial and API.
- CF metadata conventions, for coordinates, calendars, units, and missing values.
- Xarray: reading and writing files.
Disclaimer of liability
The information provided by the Earth Inversion is made available for educational purposes only.
Whilst we endeavor to keep the information up-to-date and correct. Earth Inversion makes no representations or warranties of any kind, express or implied about the completeness, accuracy, reliability, suitability or availability with respect to the website or the information, products, services or related graphics content on the website for any purpose.
UNDER NO CIRCUMSTANCE SHALL WE HAVE ANY LIABILITY TO YOU FOR ANY LOSS OR DAMAGE OF ANY KIND INCURRED AS A RESULT OF THE USE OF THE SITE OR RELIANCE ON ANY INFORMATION PROVIDED ON THE SITE. ANY RELIANCE YOU PLACED ON SUCH MATERIAL IS THEREFORE STRICTLY AT YOUR OWN RISK.
Leave a comment